arxiv 2212.08751 · Dec 2022 · MIT · OPENAIx1L
Point·E
Point clouds, efficiently. OpenAI's 2022 text-to-3D system: one synthetic view, then 1,024 points, then 4,096. A little wrong. Fast. Name from the repo point-e. Ticker POINTE. This page is a toy of the pipeline, not the weights. Not affiliated with OpenAI.
03 fine · 4,096 pts · CLIP ViT-L/14
drag to orbit
“a yellow rubber duck”
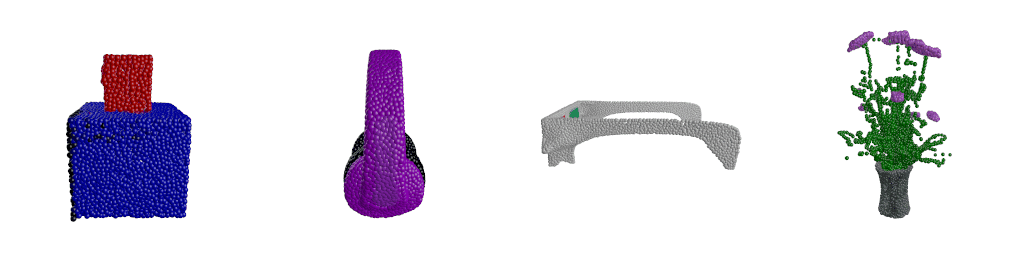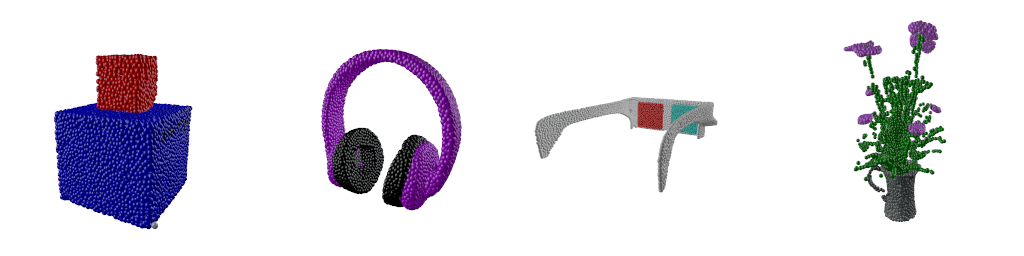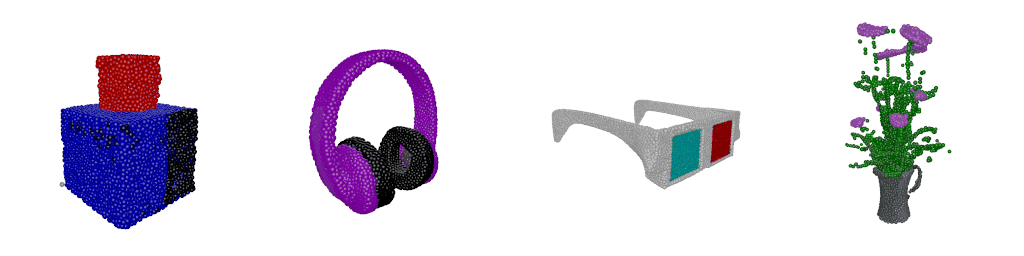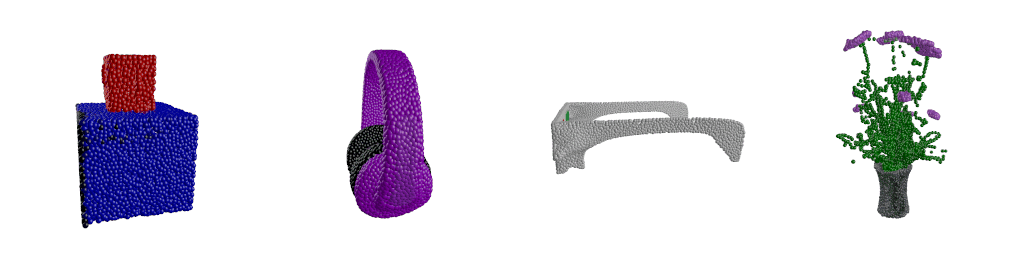
01
view
A text-to-image diffusion model draws one synthetic view from the prompt.
From the paper
“We refer to our system as Point·E, since it generates point clouds efficiently.” Nichol, Jun, Dhariwal, Mishkin, Chen. December 16, 2022.
Image-conditional stack on CLIP ViT-L/14. Text-only model is small and only gets simple categories and colors. The clouds on this page are the official 4,096-point files from banner_pcs.zip — the same ones in paper_banner.gif. We rotate them. We do not run the weights.
- repo
- openai/point-e
- ticker
- POINTE
- CA
- 0x3343052d5ac5cAC7470Bb35f815e7C378f9A1E18
- pair
- LONG × OPENAIx1L
- license
- MIT
- coarse
- 1,024 pts
- fine
- 4,096 pts
- encoder
- CLIP ViT-L/14
- notebooks
- image2pointcloud · text2pointcloud · pointcloud2mesh
What this is not
Not the released weights. Not a 1–2 minute GPU sample. Not affiliated with OpenAI. A desk toy is not yield. Figure 2 prompts are quoted; the point clouds are the MIT-licensed banner files.
Source paper and code Copyright 2022 OpenAI, MIT License. This token is not affiliated with, endorsed by, or sponsored by OpenAI.